

The On-Device AI Promise: What Stays Local—and What Doesn't
A report on what “on-device” actually means, and who gets to have it.
There is a woman in the queue at the bank who does not want the teller to know her business. She keeps her voice low when she reads out the account number, cups her hand around her mouth like a person sheltering a match from wind. It is an old instinct — the sense that what is yours should stay near you, and should not travel further than necessary. Smartphone features have never all handled information in the same way: some process it on the device, some send requests to remote services, and some sync data when a person enables backups. The details depend on the feature, the app, and its settings. On-device AI offers another way to run some tasks locally, but it does not make every interaction private by default.
On-device AI means that a model performs at least some inference on the phone or computer itself instead of sending that particular request to a remote model. Some products combine local processing with cloud services, and app or operating-system features may still transmit other data. So the useful question is not simply whether a product uses on-device AI, but which task is local, what information is passed to the app that requested it, and when a request can fall back to the cloud.
The threshold that got crossed
Some generative models require more memory and computing power than a phone can provide efficiently. Smaller models, model compression, and dedicated hardware have made selected on-device tasks practical on supported devices, but local models still have limits in capability, speed, and available memory. Those limits help explain why products may combine local inference with cloud processing rather than use one approach for every request.
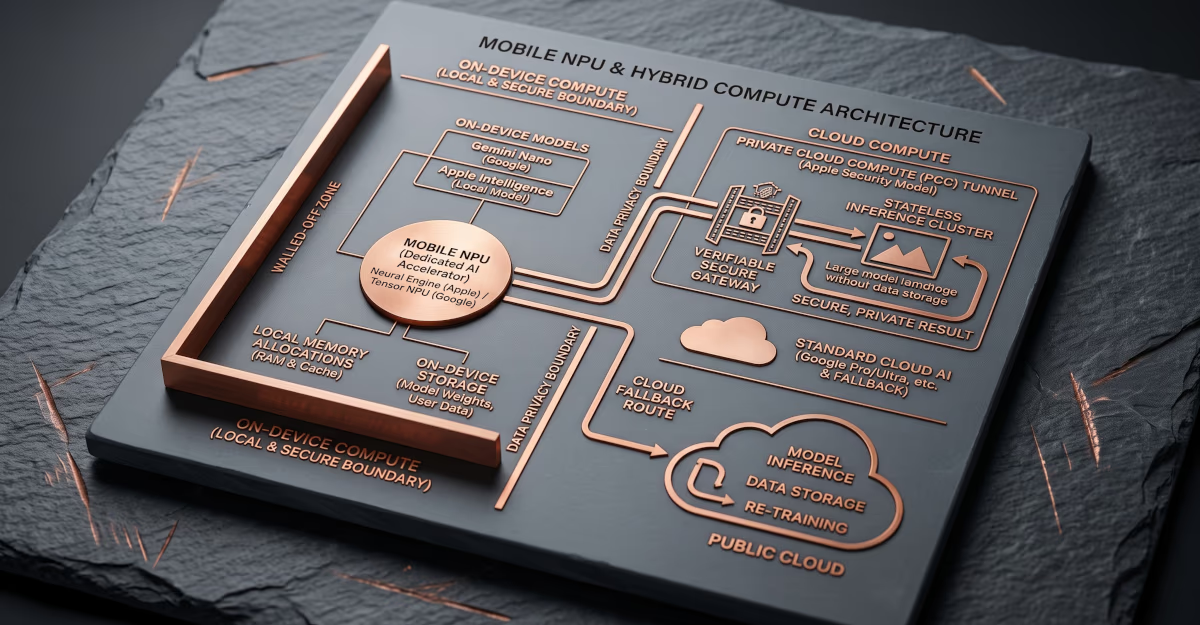
Google documents Gemini Nano as a model that runs on-device through Android's AICore on supported devices. Its documentation also describes a hybrid option that can route a request to a cloud model when Nano is unavailable or cannot handle the task. Apple describes a similar split for Apple Intelligence: on-device processing for many requests, with Private Cloud Compute for some requests that need larger models. Both companies' descriptions are product-specific; they should not be read as a promise that every AI feature or every request stays local.
The move toward local inference changes the trade-offs for device makers and app developers: some work can happen without a network round trip, while model size, power use, device support, and cloud fallbacks still matter. These are engineering choices that vary by product, not evidence that all smartphones—or all AI features—have moved away from cloud services.
What the promise looks like, kept
When an application performs a task locally, that request does not need to be sent to a remote model for inference. Google's Android documentation describes Gemini Nano as an on-device option for supported use cases, and Apple describes on-device processing as part of Apple Intelligence. This can reduce the information sent to a cloud model for those tasks. It does not by itself establish what an app stores, shares, or backs up, and the details vary by feature and device.
“On-device” describes where a particular computation occurs; it does not describe the whole data lifecycle. Google's documentation explicitly distinguishes on-device Gemini Nano from a hybrid option that can route requests to a cloud model. Apple's Private Cloud Compute is a separate cloud system for some requests, and Apple publishes security information about its design. These product descriptions are not interchangeable, and an individual feature's processing path should be checked in the documentation for that feature.
The terms “private,” “on-device,” and “local” are not substitutes for a feature-level explanation. A clear description should distinguish local processing from cloud processing and explain what the app or service receives, retains, or synchronizes.
What a browser feature can show
Chrome's Prompt API is one concrete example of why local inference does not answer every privacy question. Chrome's developer documentation says the API uses Gemini Nano and that the model is downloaded separately when an origin first uses it. A website or extension that calls the API supplies the prompt and receives the model's response in its own code. The model can run locally while the site that requested a result still handles the information it submitted or received.
This is not evidence that a local model secretly sent its prompt to a cloud service. It is a reminder that the party invoking a local model may still have access to the data passed through its own code. Users and developers should distinguish between where inference takes place and which application supplied the prompt, receives the output, or may store it.
Local execution can reduce the need to transmit a particular input to a remote model, but it does not establish whether an application stores or synchronizes data elsewhere. The Chrome API documentation also makes the boundaries of its model use explicit: the model runs locally, but a website or extension using the API still controls the prompt and receives the output. “On-device” describes where inference happens; it does not, by itself, explain what the surrounding application does with information.
The class of phone that gets to be private
Access to on-device features depends on the device, operating-system version, language, and feature. Apple publishes a compatibility list for Apple Intelligence, while Google documents device and hardware requirements for its on-device APIs. Those lists can change as products and software are updated; it is not accurate to infer from a phone's price alone that its requests are routed to the cloud.
Device eligibility can affect who gets particular local features, but local processing is not a complete measure of privacy. A more useful comparison asks which devices support a feature and what happens to its inputs and outputs on-device, in the calling app, and in any cloud fallback.
What is actually true, said plainly
None of this means on-device processing is a mirage. It can allow supported tasks to run without sending that request to a remote model, and may reduce latency or network use. Privacy still depends on the whole system: which component receives the input and result, what is retained, whether data is synchronized, and whether the feature can use a cloud fallback.
The accurate version is narrower: some tasks can run locally on supported devices, while other requests use cloud services or a hybrid path. A product's settings and documentation should explain which applies. Local processing is a meaningful privacy property, but it should not be treated as a blanket promise about every feature or every piece of data.
What is left to ask
The useful questions are feature-specific: what is processed locally, what is sent to a cloud service, and which app or website receives the prompt and result? Is a cloud fallback available, and how is it disclosed? What data is stored or synchronized? These details matter more than a general label such as “on-device.”
The woman at the bank still has a reasonable question: when she asks her phone something private, where does the request go, and who can see the response? The answer depends on the feature she uses. That is why clear, current explanations of processing paths matter as much as the model running on the device.
Sources
Primary references: Google's Gemini Nano and AICore documentation and Chrome Prompt API documentation; Apple's Apple Intelligence compatibility information and Private Cloud Compute security overview. Feature availability and processing paths vary by device, region, language, and software version.